A Framework for Measuring Quality of AI-Generated Regulatory Submission Content 

Aug 11, 2026by Weave Team

In a previous blog, we made the case that hallucinations aren’t a glitch to be patched out of a model, but a predictable consequence of how these systems are trained. We closed that piece with a claim that deserves more scrutiny: that Weave measures quality through a combination of rigorous experimentation and real-world user behavior, rather than relying on a model’s ability to sound convincing.

This piece goes one level deeper: what does it take to measure the quality of AI-generated content for regulatory submissions, and how can the tools the rest of machine learning relies on be adapted for this use case?

Adapting standard LLM quality metrics for regulatory submission content

The standard toolkit for evaluating classification by a machine learning model is precision and recall. Did the model correctly flag what needed flagging? Did it miss anything? These metrics work beautifully when a model’s job is to make a discrete call: verify this data point, tag this document, flag this anomaly. There’s a ground truth to check against. The answer is right or it isn’t.

Long-form content generation is more complex. When a model drafts a clinical overview section or synthesizes a study summary, there’s no single correct answer to check against — there’s a space of acceptable outputs, and a much larger space of outputs that are subtly, unacceptably wrong. “Was this generated section correct?” isn’t a yes/no question the way “was this data point tagged correctly?” is.

To evaluate generation tasks, NLP experts have historically used graded rather than binary metrics: n-gram overlap measures like ROUGE and BLEU, embedding-based similarity like BERTScore, and structured human rubrics with inter-annotator agreement as the reliability check. Other off-the-shelf evaluation frameworks, such as RAGAS, include metrics for faithfulness, relevance, and adherence.

Deploying generative AI in Weave’s customer environments required adapting these and other metrics to measure the quality of regulatory submission content. In drug development and other regulated industries, the discipline of evaluating whether an AI system is good at its job is still being invented, in real time, by the teams building on the frontier. We encourage our peers in the space to share their feedback on our framework and continue openly circulating their ideas.

Breaking AI quality into measurable dimensions: faithfulness, adherence, and more

The first step was refusing to treat “quality” as one fuzzy, holistic judgment. A single up-or-down vote from a human reviewer tells you almost nothing about why something went wrong or how to fix it. And when that vote comes from an LLM grading its own kind, it can tell you less than nothing. Each problem has a different answer. 

We address the first by decomposing quality into the distinct, independently measurable dimensions, each targeting a specific failure mode we’ve a) observed in production, and b) validated with regulatory writers to confirm that they are in fact valuable to measure. 

We address the second with independence: our evaluators come from a different model family than the models doing the writing, and they run at zero temperature — so a change in score reflects a change in the system, not a reroll of the dice.
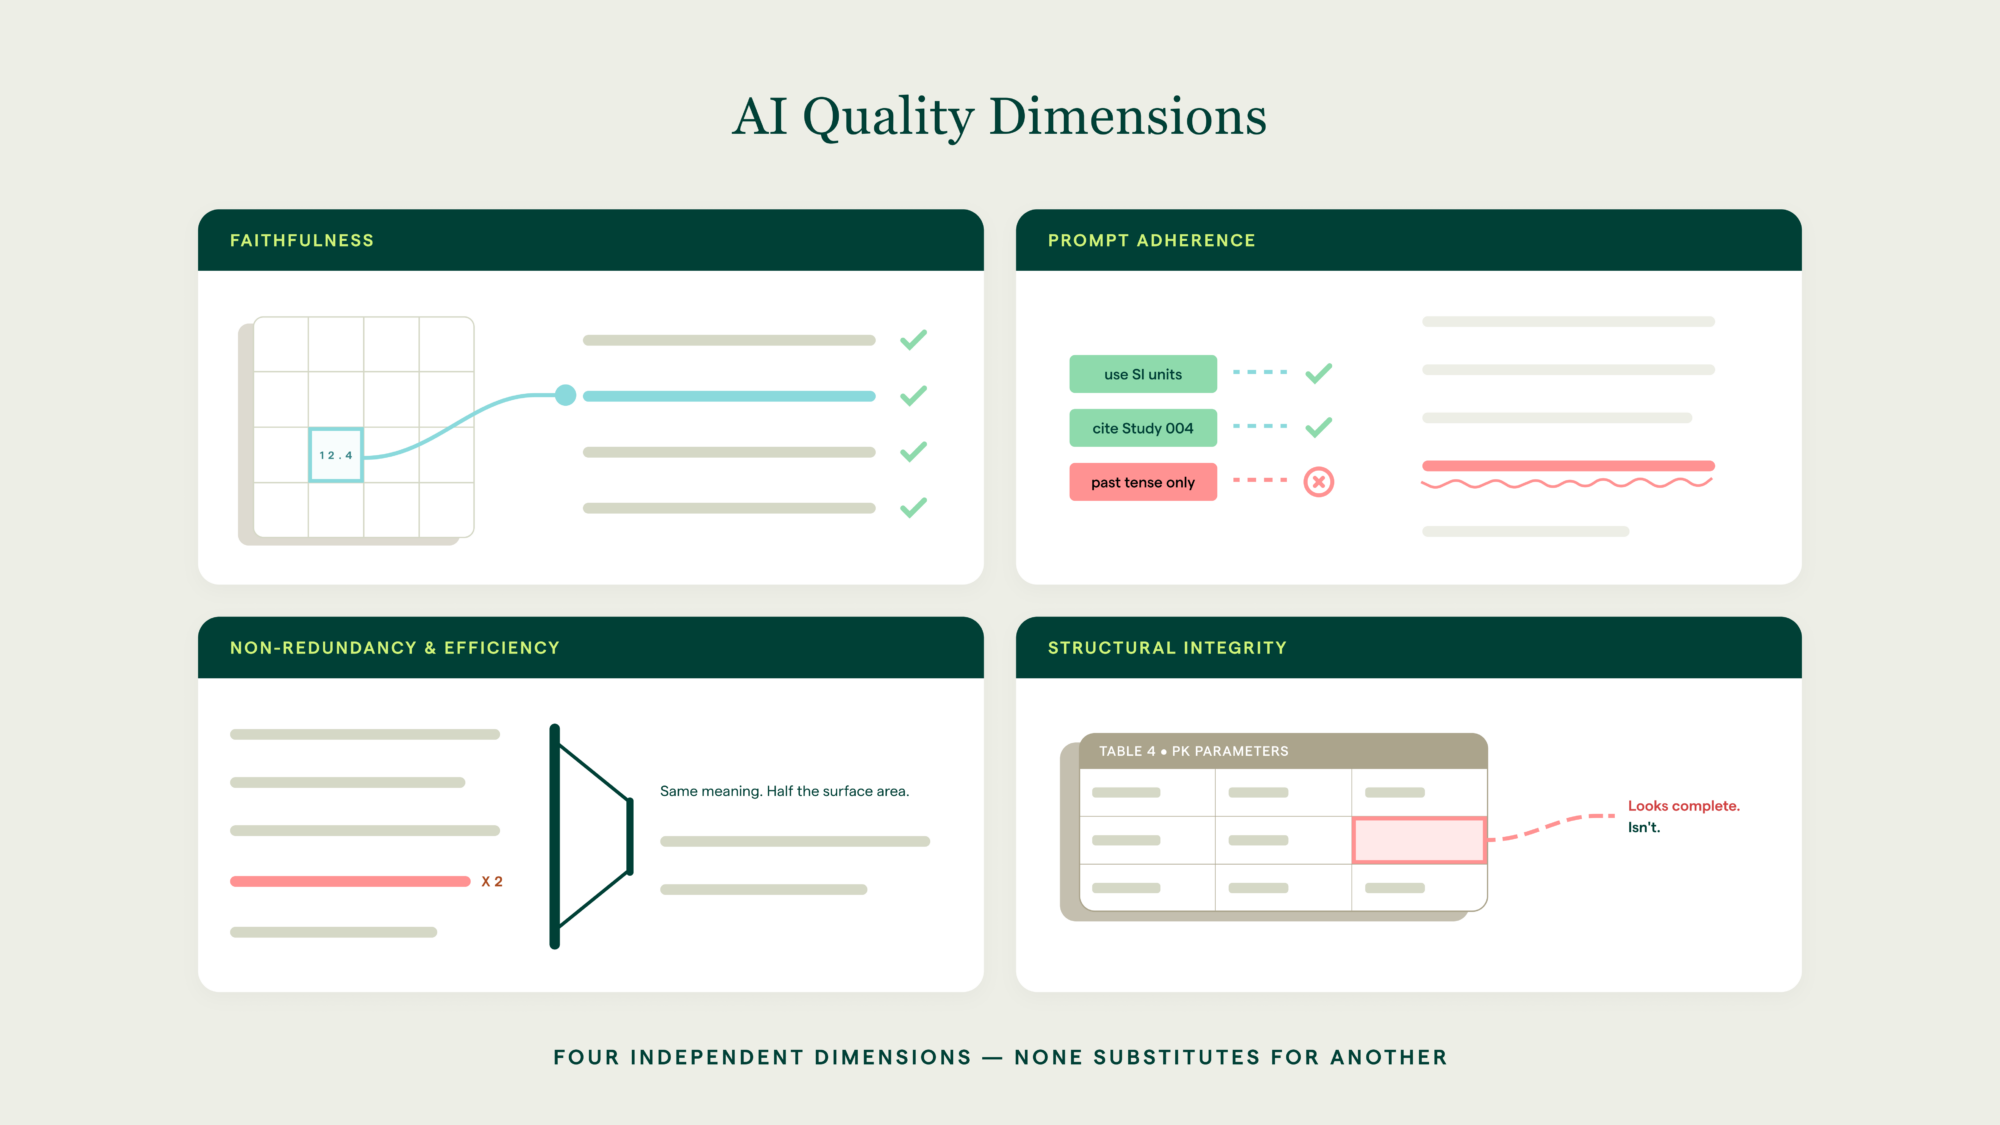
Graphic representing four types of AI Quality dimensions: faithfulness, prompt adherence, non-redundancy and structural integrity
A few examples of what we track and why each one matters in regulatory writing:
  • Faithfulness asks whether generated content actually matches its source material. This is the throughline from our hallucination piece: faithfulness errors happen when a model has the right source in front of it but still distorts it. We evaluate this at a granular level, sentence by sentence and, for tables, cell by cell, rather than asking for one verdict on an entire document. A single unfaithful sentence buried in an otherwise accurate ten-page section is exactly the kind of error a document-level check would miss — and exactly the kind that matters most in a regulatory filing.
  • Prompt adherence asks whether the model did what it was actually asked to do. In regulatory authoring, instructions are rarely simple. So we don’t ask an evaluator to render one verdict on a complex instruction. We break the instruction into its component parts and check each one independently. The result isn’t a single adherence score — it’s a diagnosis of exactly which part of the instruction was missed.
  • Non-redundancy and efficiency ask whether the draft repeats itself, and whether it says what it needs to in as few words as possible. This isn’t a style preference. Every redundant sentence is a sentence a reviewer has to read, question, and reconcile against everything else in the dossier. Measuring efficiency is measuring how much unnecessary surface area for inconsistency we’ve left in a document.
  • Structural integrity checks whether tables render properly and whether they’re titled. Do they have titles? Do the outputs merely look complete on a scan, or are they actually complete? These are the unglamorous checks that rarely make it into a product demo but reliably make it into a real production incident if they’re skipped.

More recently, we began experimenting with metrics for technical writing quality. These have not yet been validated by specific individuals, but reflect general feedback we’ve received from users.

  • Clarity asks whether a regulatory reviewer can understand each sentence on first reading, and whether the prose is lean: short direct sentences carrying one or two thoughts, active voice where the actor is known, paragraphs that open with a topic sentence and follow a single line of reasoning, and no filler (“it should be noted that”, “due to the fact that”).  
  • Emphasis asks whether the right things are prominent. It scores whether the most pivotal data gets proportional space and position, led in topic sentences rather than buried mid-paragraph, so the reader comes away with an accurate reading of the pivotal messages.

None of these dimensions substitutes for the others. A section can be faithful to its source and still redundant. It can be efficient and still miss half the instruction. True quality assessment means tracking all of these continuously.

Who grades the grader? Validating LLM evaluators against human judgment

The harder problem underneath all of this: most of these dimensions can’t be measured with a simple rule-based check. Faithfulness, adherence, and redundancy all require judgment, which means we’re using an LLM to evaluate the output of another LLM. We don’t take that arrangement on faith.
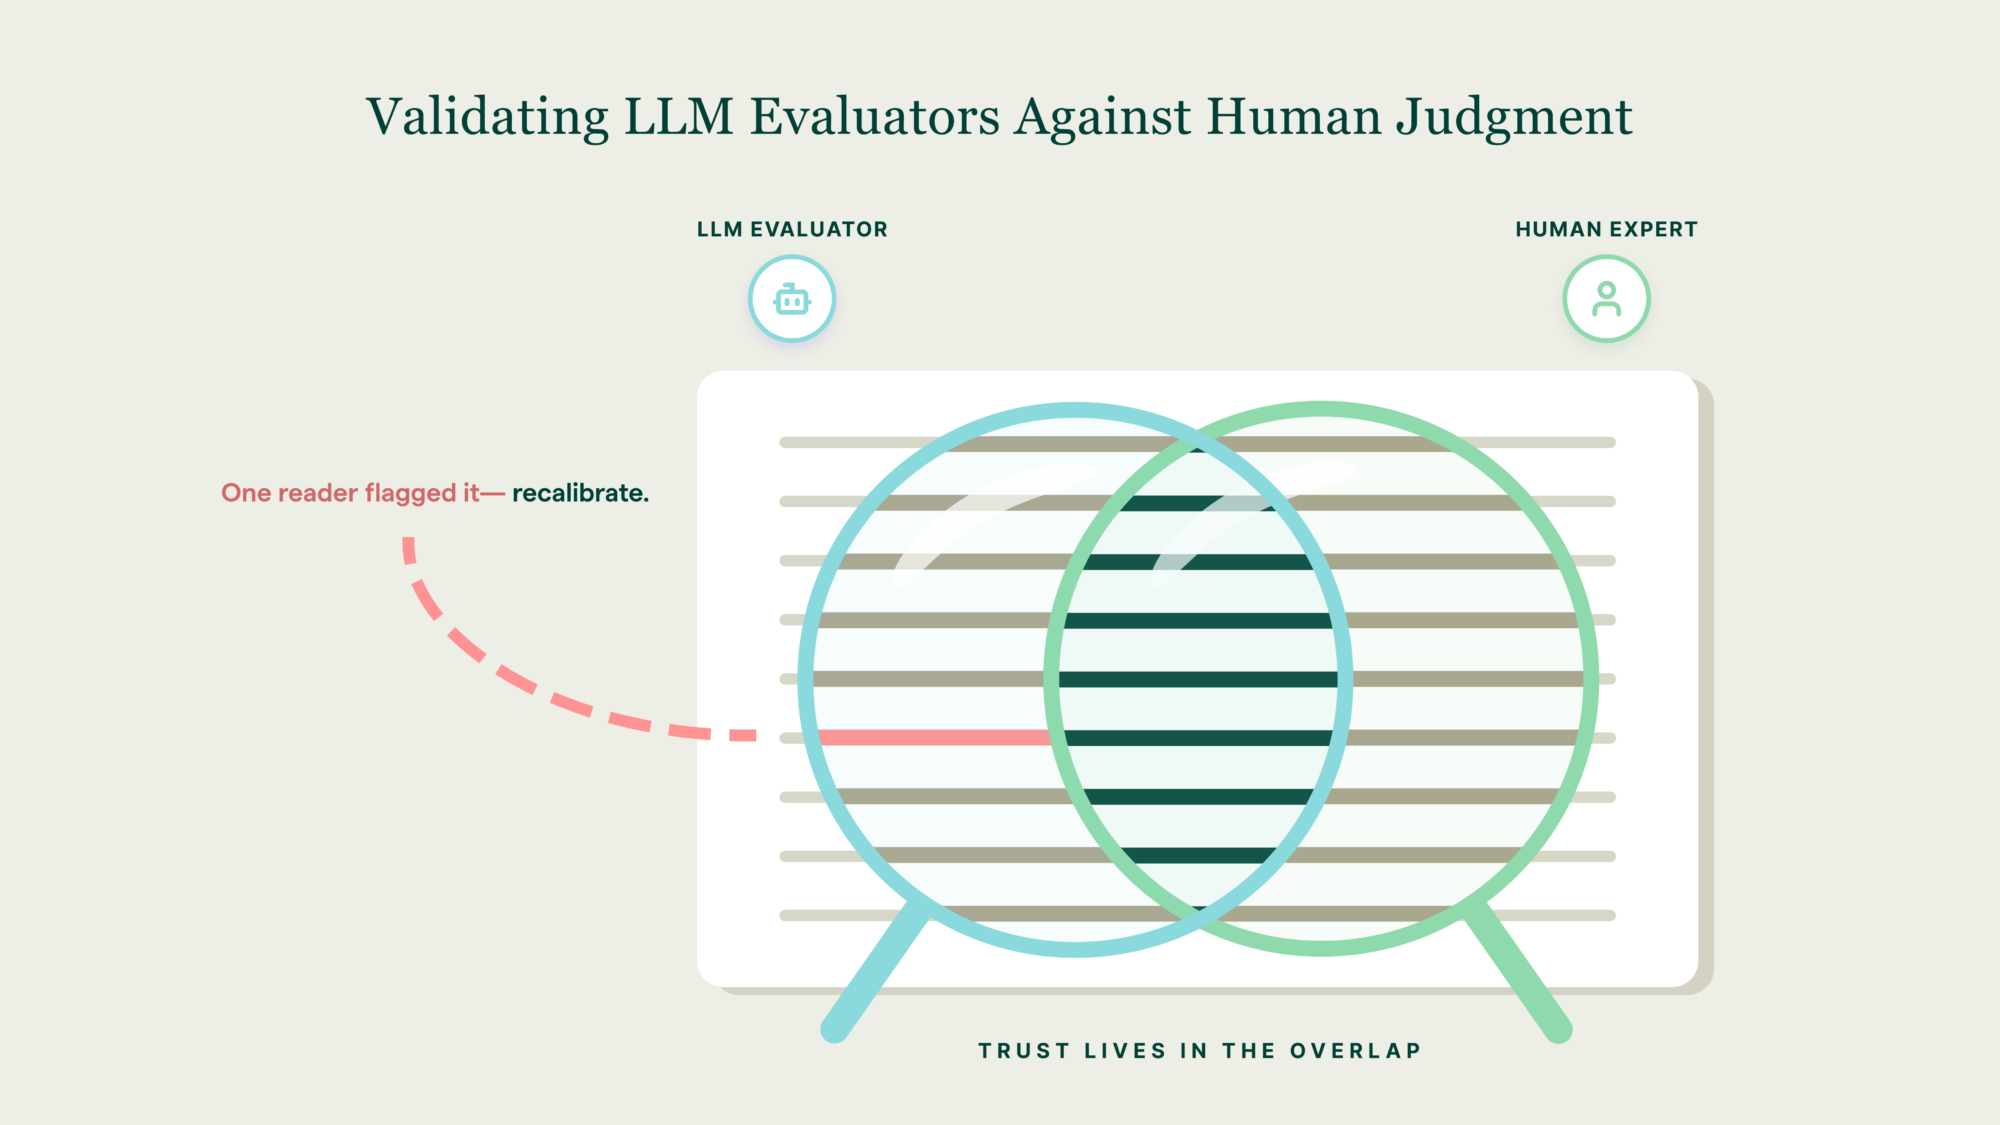
Graphic showing overlap between LLM evaluator and human expert judgment

An LLM evaluator is only useful if it agrees with what a knowledgeable human would conclude. We validate evaluator judgments directly against human assessments of the same content. And that validation isn’t a one-off annotation exercise. Reviewers confirm or flag AI-verified content at the same granularity the evaluator works at — sentence by sentence, cell by cell — and a human decision always overrides an automated one.

Every one of those actions is a human judgment on a machine judgment about the same words, accumulating continuously, on real submissions. Every time we make a significant change to the system — a model upgrade, a change to a pipeline that feeds the model context — we rerun the evaluation. Quality measurement is not a certification we earn once. It’s a discipline we repeat, because the alternative is discovering a regression after it’s already shipped.

Beyond the lab: measuring AI quality with real-world usage signals

Experimentation measures performance under controlled conditions. It doesn’t measure performance once real users, with real deadlines and real documents, are actually using the system. That’s why we also track user actions directly in the product: does a reviewer accept or reject an AI-suggested revision? Add or delete a data tag the model proposed? Flip a verification flag the model set?

Each of these is a small, real signal about whether the system is doing its job. Unlike a controlled experiment, it’s happening continuously, in production, on real content, for as long as the feature is live.

We’re also direct about the limits of this signal. A user not overriding a suggestion doesn’t mean the suggestion was correct. It might just mean no one looked closely. These signals are structurally better at catching what the model got wrong, which a user can flag, than what the model should have done but didn’t, since there’s nothing on the screen to react to. Any vendor telling you their usage metrics capture the full picture of quality either hasn’t thought carefully about this or isn’t being straight with you. We track it anyway, because an imperfect real-world signal is still more valuable than no real-world signal — but we treat it as one input among several, not a verdict.

“Why can’t I just use my own ChatGPT for this?”

This question comes up often, and it deserves a real answer.

A frontier LLM accessed through a general-purpose chat interface can absolutely produce fluent, plausible regulatory content. 

What that interface doesn’t give you is any of the above. No faithfulness scoring against your source documents. No sentence-level or cell-level QC. No calibration discipline verifying that the system’s self-assessment tracks human judgment. No instrumentation showing you where, across your team’s real usage, the system is quietly underperforming. You get an output. You don’t get a measurement system telling you whether to trust it, and you don’t get a feedback loop that improves it based on how your team actually works.

The model itself is table stakes, and it’s becoming less differentiated by the month as frontier labs converge on similar capability. What doesn’t come bundled with API access is the infrastructure to know, with evidence, whether a piece of output belongs in your regulatory filing. That infrastructure isn’t a feature we added. It’s the product.

Rigor over marketing: why AI quality measurement matters in drug development

In drug development, the standard is whether the output holds up under intense scrutiny from a reviewer, an auditor, a health authority. One unsupported claim can trigger a review cycle. There is no version of “close enough” that survives that environment.

We measure quality this way because our customers can’t afford for us to guess, and because at our core, we are scientists too. It means something to put your name behind a claim, and part of that is showing your work.

To learn more about how leading regulatory teams are applying quality frameworks in practice, register for our webinar on August 19. We’ll draw on Weave’s real-world collaboration with Takeda to share the playbook for scaling AI in drug development without sacrificing rigor.
The Rebuild Tax: How Connected Source Data Changes the Economics of Global Submissions

Jun 30, 2026by Weave Team

Global regulatory submissions rarely follow a clean sequence. Every drug development team knows the anxiety of planning the next filing while the first is still in progress — for a team starting in the US, the stress of completing an IND hasn’t subsided when the questions start. Will the program run a later-stage trial in Europe? Are we already behind on the CTA?

The underlying science and data package are largely consistent across markets, with jurisdiction-specific requirements layered on top, but the effort of reformatting, retranslating, and reconstructing that package for each submission adds up fast. As programs reach later stages, the effort that goes into packaging and presenting data in different submissions and languages begins to eclipse development work itself. Not only is this a burden on writers, but it pulls SMEs away from validating assays and planning pivotal trials.

This is the rebuild tax. It doesn’t show up as a line item in a budget, but it’s real — paid in weeks of duplicated effort, in the compounding risk of version misalignment across jurisdictions, and in the quiet cost of senior scientists and regulatory experts spending their time copy/pasting and reformatting instead of doing strategic work that requires their expertise.

Why Global Submissions Get Rebuilt From Scratch

The rebuild tax doesn’t exist because teams are doing something wrong. It happened because the tools available assumed a single-jurisdiction world. Documents were authored in isolation. Dossiers lived in folders, not platforms. There was no structural concept of “source of truth” — just a set of files that got adapted, jurisdiction by jurisdiction, filing by filing.

The biotechnology industry is relatively young, as are global regulations. The idea of developing one drug in one country and marketing internationally is even younger. Even the idea of data as an abstract entity — something that exists on hard drives, organized into schemas, or served up via MCP, separate from documents and paper — is decades old at most.

The runaway work of submitting a drug to many jurisdictions, and the patchwork solutions that are used to manage this process today, are only the status quo because of inertia. 

Documents are passed around on Sharepoint. Amendments start to outnumber initial submissions. Everyone wants consistency, but no one can follow how every update in the latest IND amendment should, or should not, propagate into future CTA submissions. Comment chains get longer and longer, and the data that can answer a question is often on someone’s laptop, or in a hidden shared drive. Even with a perfectly organized RIM system, documents are disconnected and require manual sorting and review.

By the time of pivotal trials, the program’s data and document footprint is far beyond what any one person can actually understand, manage, and trust. 

Looking at this process from the outside, it’s easy to ask: why is it like this? And the answer isn’t rooted in science or a technological limitation. But with the commercialization of LLMs, there’s never been a better time to imagine what a regulatory knowledge management system should look like. 

What the Rebuild Tax Actually Costs

When every submission is treated as a discrete event rather than part of a connected program, rebuilding from scratch is the default. You work from what you have, which is usually the last filing, manually cross-reference with new data, and hope that the next submission contains the right mix of previously approved content and updated data. 

The problem compounds across time. A Phase 1 IND becomes a Phase 2 amendment becomes an NDA. Each filing draws on the previous one, but without a live connection to the underlying source data, the dossier you’re working on starts to feel like a form that’s been Xeroxed too many times.

The direct cost is labor: hours spent re-formatting, re-mapping and re-verifying content that already exists elsewhere. Predictably, this problem accelerates with a program’s success: the more successful your drug, the bigger the challenge of keeping its regulatory lifecycle in order. The more at stake, the harder it is to keep the program data and narrative cohesive. The administrative cost of a late-stage program is staggering. Improving this isn’t about copying documents, it requires routing and synchronizing data flawlessly for a decade.

The indirect costs are harder to quantify but often larger. Errors introduced during manual reformatting. Inconsistencies between what was filed in the US and what was filed in Europe. Delays in getting to a health authority because the submission team is still reconstructing the dossier. Each of these has downstream consequences — on timelines, on review cycles, on the resources consumed before a therapy reaches patients.

A Different Structural Assumption

The rebuild tax is not inevitable. It’s a consequence of a particular architecture: one where submissions are outputs rather than nodes in a connected system. But when we think of submissions as stacks of documents, copied again and again, we spend more on administration than on development.

The alternative starts from a different premise: A program is a continuously evolving model of a disease state and its treatment. Each study, whether an accelerated stability study run in a basement lab, or a pivotal trial run in a university hospital – adds new nodes to the data foundation for that model.

Approaching drug development this way requires tooling beyond just document storage and approval workflows, beyond just generating an eCTD with AI. It requires a system that can connect data and action automatically, starting with simple pathways and extending them into a complex nervous system as a program grows.

Each completed filing, in this model, becomes a reusable reference point for the next one. The system becomes smarter, and its users become more informed.

Reusing Content Across Jurisdictions in Practice

While the data is the same, every jurisdiction is slightly different in formatting expectations, even within ICH and eCTD-aligned regions. Can a document used in the US be re-used verbatim in the EU? Or, does it require small tweaks, which means it is now a new document, with a new review and approval process?

The answer: it depends. Below are two examples showing how this plays out in practice.

Example 1: The Investigator’s Brochure

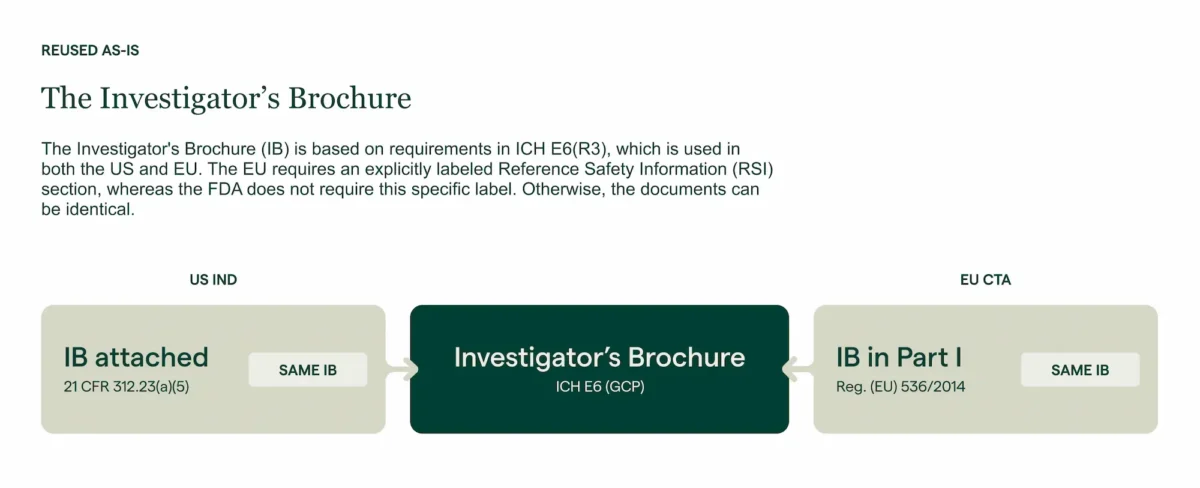
An Investigator’s Brochure (IB) is largely the same document, governed under ICH E6 (R3). This document is one of the easiest to re-use across different regions, in part because guidelines are directly laid out in an ICH standard, and in part because the ultimate audience is an investigator, not a regulator. The IB is effectively a pure compilation of knowledge, intended to inform scientifically versus tell a story for approval. However, it still can vary slightly across jurisdictions.

Diagram showing how the Investigator's Brochure is applied in US IND and EU CTA submissions.

Example 2: Chemistry, Manufacturing and Controls (CMC) Content

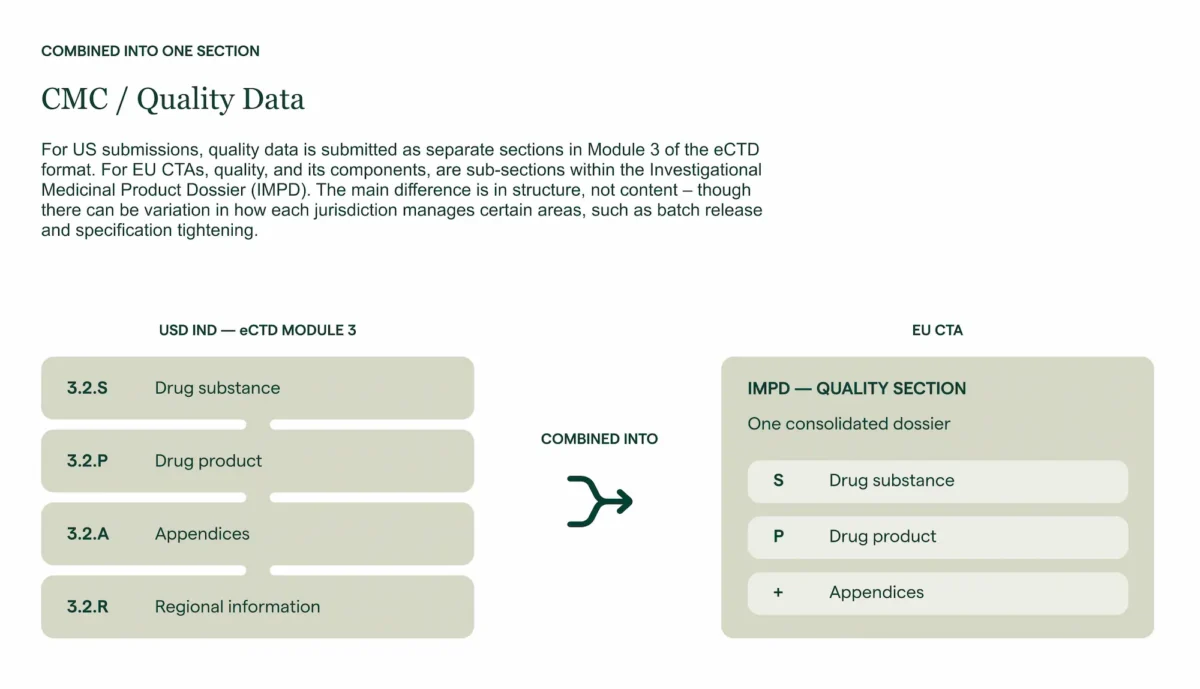
Chemistry, Manufacturing and Controls (CMC) sections are structured differently between the US and Europe. In the US, the CMC information is detailed in Module 3, following ICH standards (M4Q) as part of the eCTD structure. In a CTA in Europe, the format expected by CTIS is the Investigational Medicinal Product Dossier (IMPD). A sub-portion of the IMPD covers quality. While the underlying data still remains the same, the structure is quite different: a hierarchical module structure in the US, a single extensive dossier in the EU. Re-formatting this data in one direction or the other may actually be more difficult than building from scratch, and the task of keeping Module 3 and an IMPD in sync over a decade while a program matures is substantial.

Diagram showing how CMC quality data is compiled in Module 3 of the US IND and in the IMPD of the EU CTA.

The limits of planning

Given these differences, it’s natural to try to plan for re-usability. Even if the formats are different across jurisdictions, can you structure the documents in each jurisdiction so that re-using them is as simple as possible? Often, yes. But this requires you to know ahead of time what you’re building for, which adds planning overhead and coordination.

Planning reduces the burden, but it doesn’t remove it. Re-use is achievable when source data is structured with portability in mind. The ceiling is administrative content: labeling, patient-facing materials, and submission content that health authorities require in local languages introduce genuine jurisdiction-specific work that templates can’t absorb. The practical implication is that the value of a connected data foundation isn’t measured in documents re-used verbatim — it’s measured in how little has to be rebuilt from scratch each time a new jurisdiction is added to the program.

Building a Submission Infrastructure That Travels 

Not every program starts off crossing borders, but most successful drugs are marketed across more than one country. For regulatory teams planning international programs, the question worth asking is not just ‘how do we file in the EU?’ It’s ‘how do we build a program infrastructure that doesn’t charge a rebuild tax every time the program crosses a border?’

That framing shifts the evaluation criteria. A platform that supports global submissions isn’t just about having the right templates — it’s about whether source data is connected, whether verified content travels with the program, and whether the work done today compounds into something useful for every filing that follows.

When every submission is built from the same source data, and every past filing can be cross-referenced for lessons learned and questions answered, the tradeoff between early-stage speed and long-term infrastructure disappears. 

The science doesn’t change when a program crosses a border. The submission structure does — and the teams that stop paying the rebuild tax every time that happens are the ones who get to the finish line first.


Weave Bio’s global submission capabilities are available now, including a pre-loaded EU CTA template built to EMA-compliant section hierarchies and a custom template builder for any health authority worldwide.